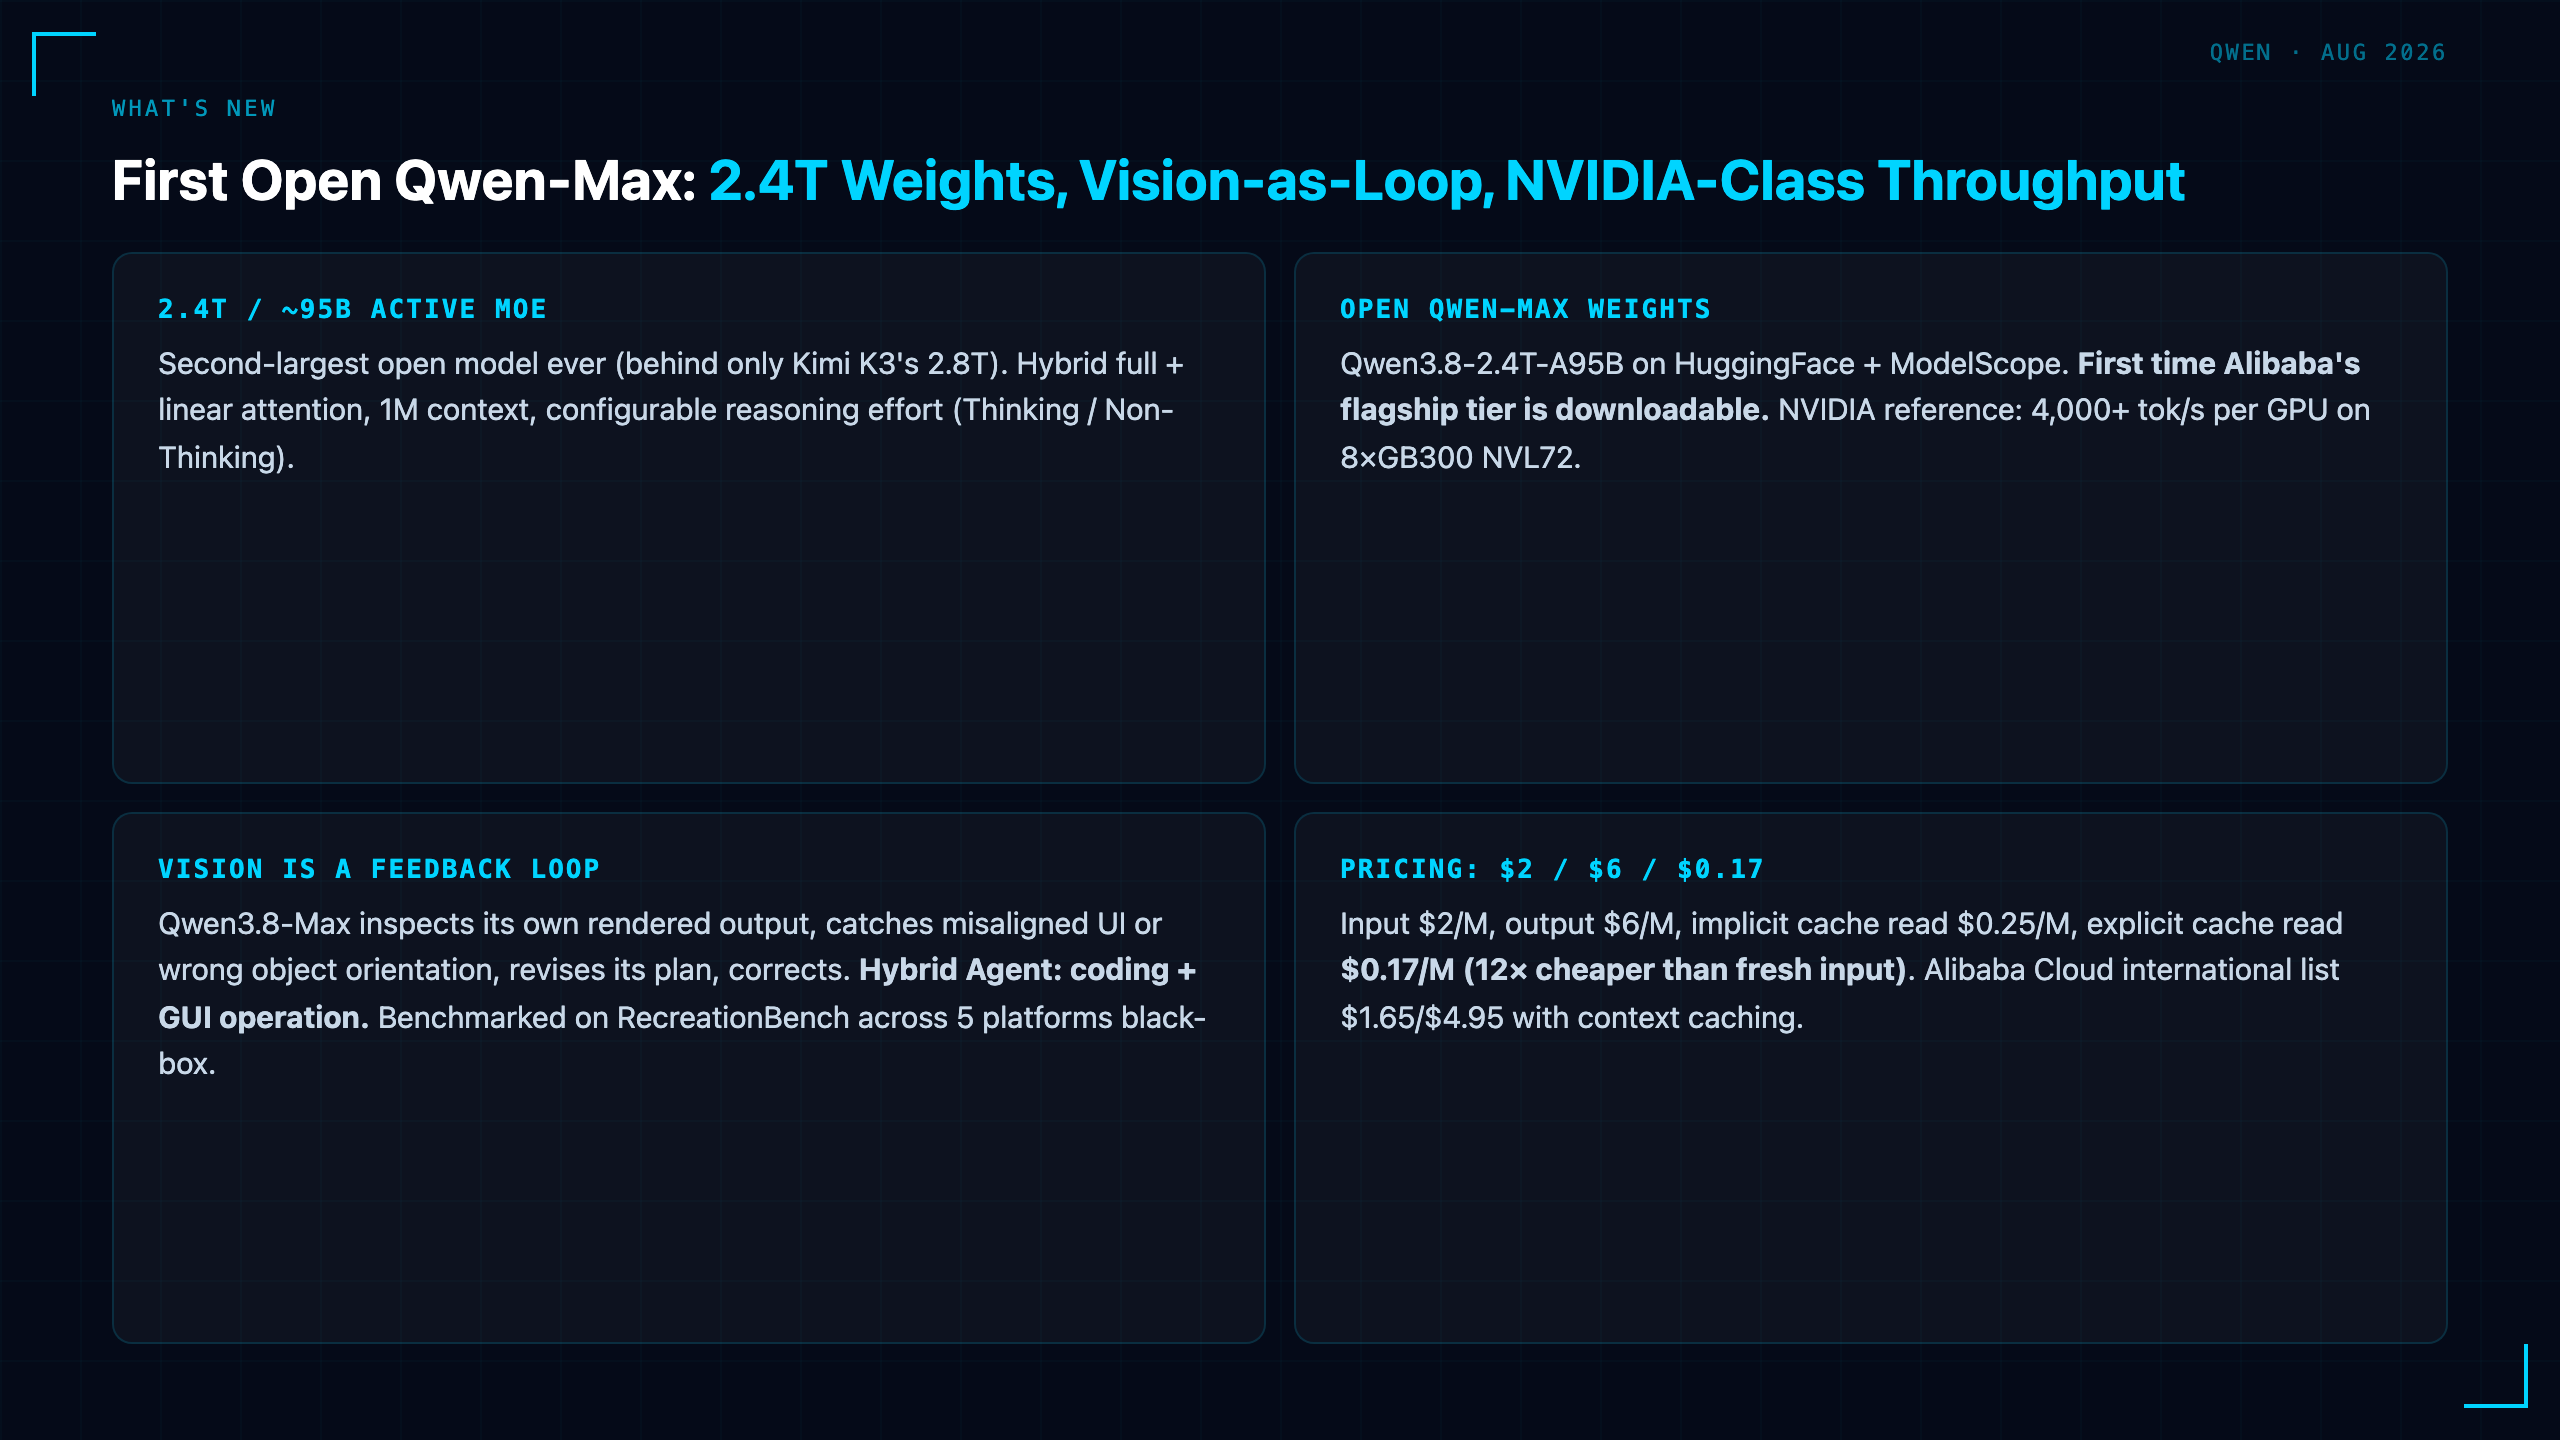
On September 2, 2026, the Qwen team at Alibaba did something that should look familiar by now: they shipped a date-suffix snapshot of their flagship model, and the coding leaderboards reshuffled. Qwen3.8-Max-0902 is not a new model generation. It is the same 2.4-trillion-parameter MoE with 95B active parameters and a 1M-token context window that launched on August 3, with one targeted post-training pass focused on coding and long-horizon Cowork agent work. Same architecture, same price, free upgrade for anyone already on qwen3.8-max.
The headline number is 1,691. That is the Elo on CodeArena WebDev, the front-end coding leaderboard run by Arena.ai, where the 0902 snapshot debuted at first place — 3 points ahead of Claude Opus 5 Max (1,687), 17 ahead of Kimi K3 Max (1,674), and 22 ahead of the August Qwen3.8-Max (1,669). Three points on an Elo scale is inside the measurement noise. The more interesting story is underneath: a cluster of agentic coding benchmarks more than doubled in a single post-training pass, and the model now leads Claude Opus 5 on several of them while still costing a fifth as much.
What's New: Coding + Cowork Post-Training, No Architecture Change
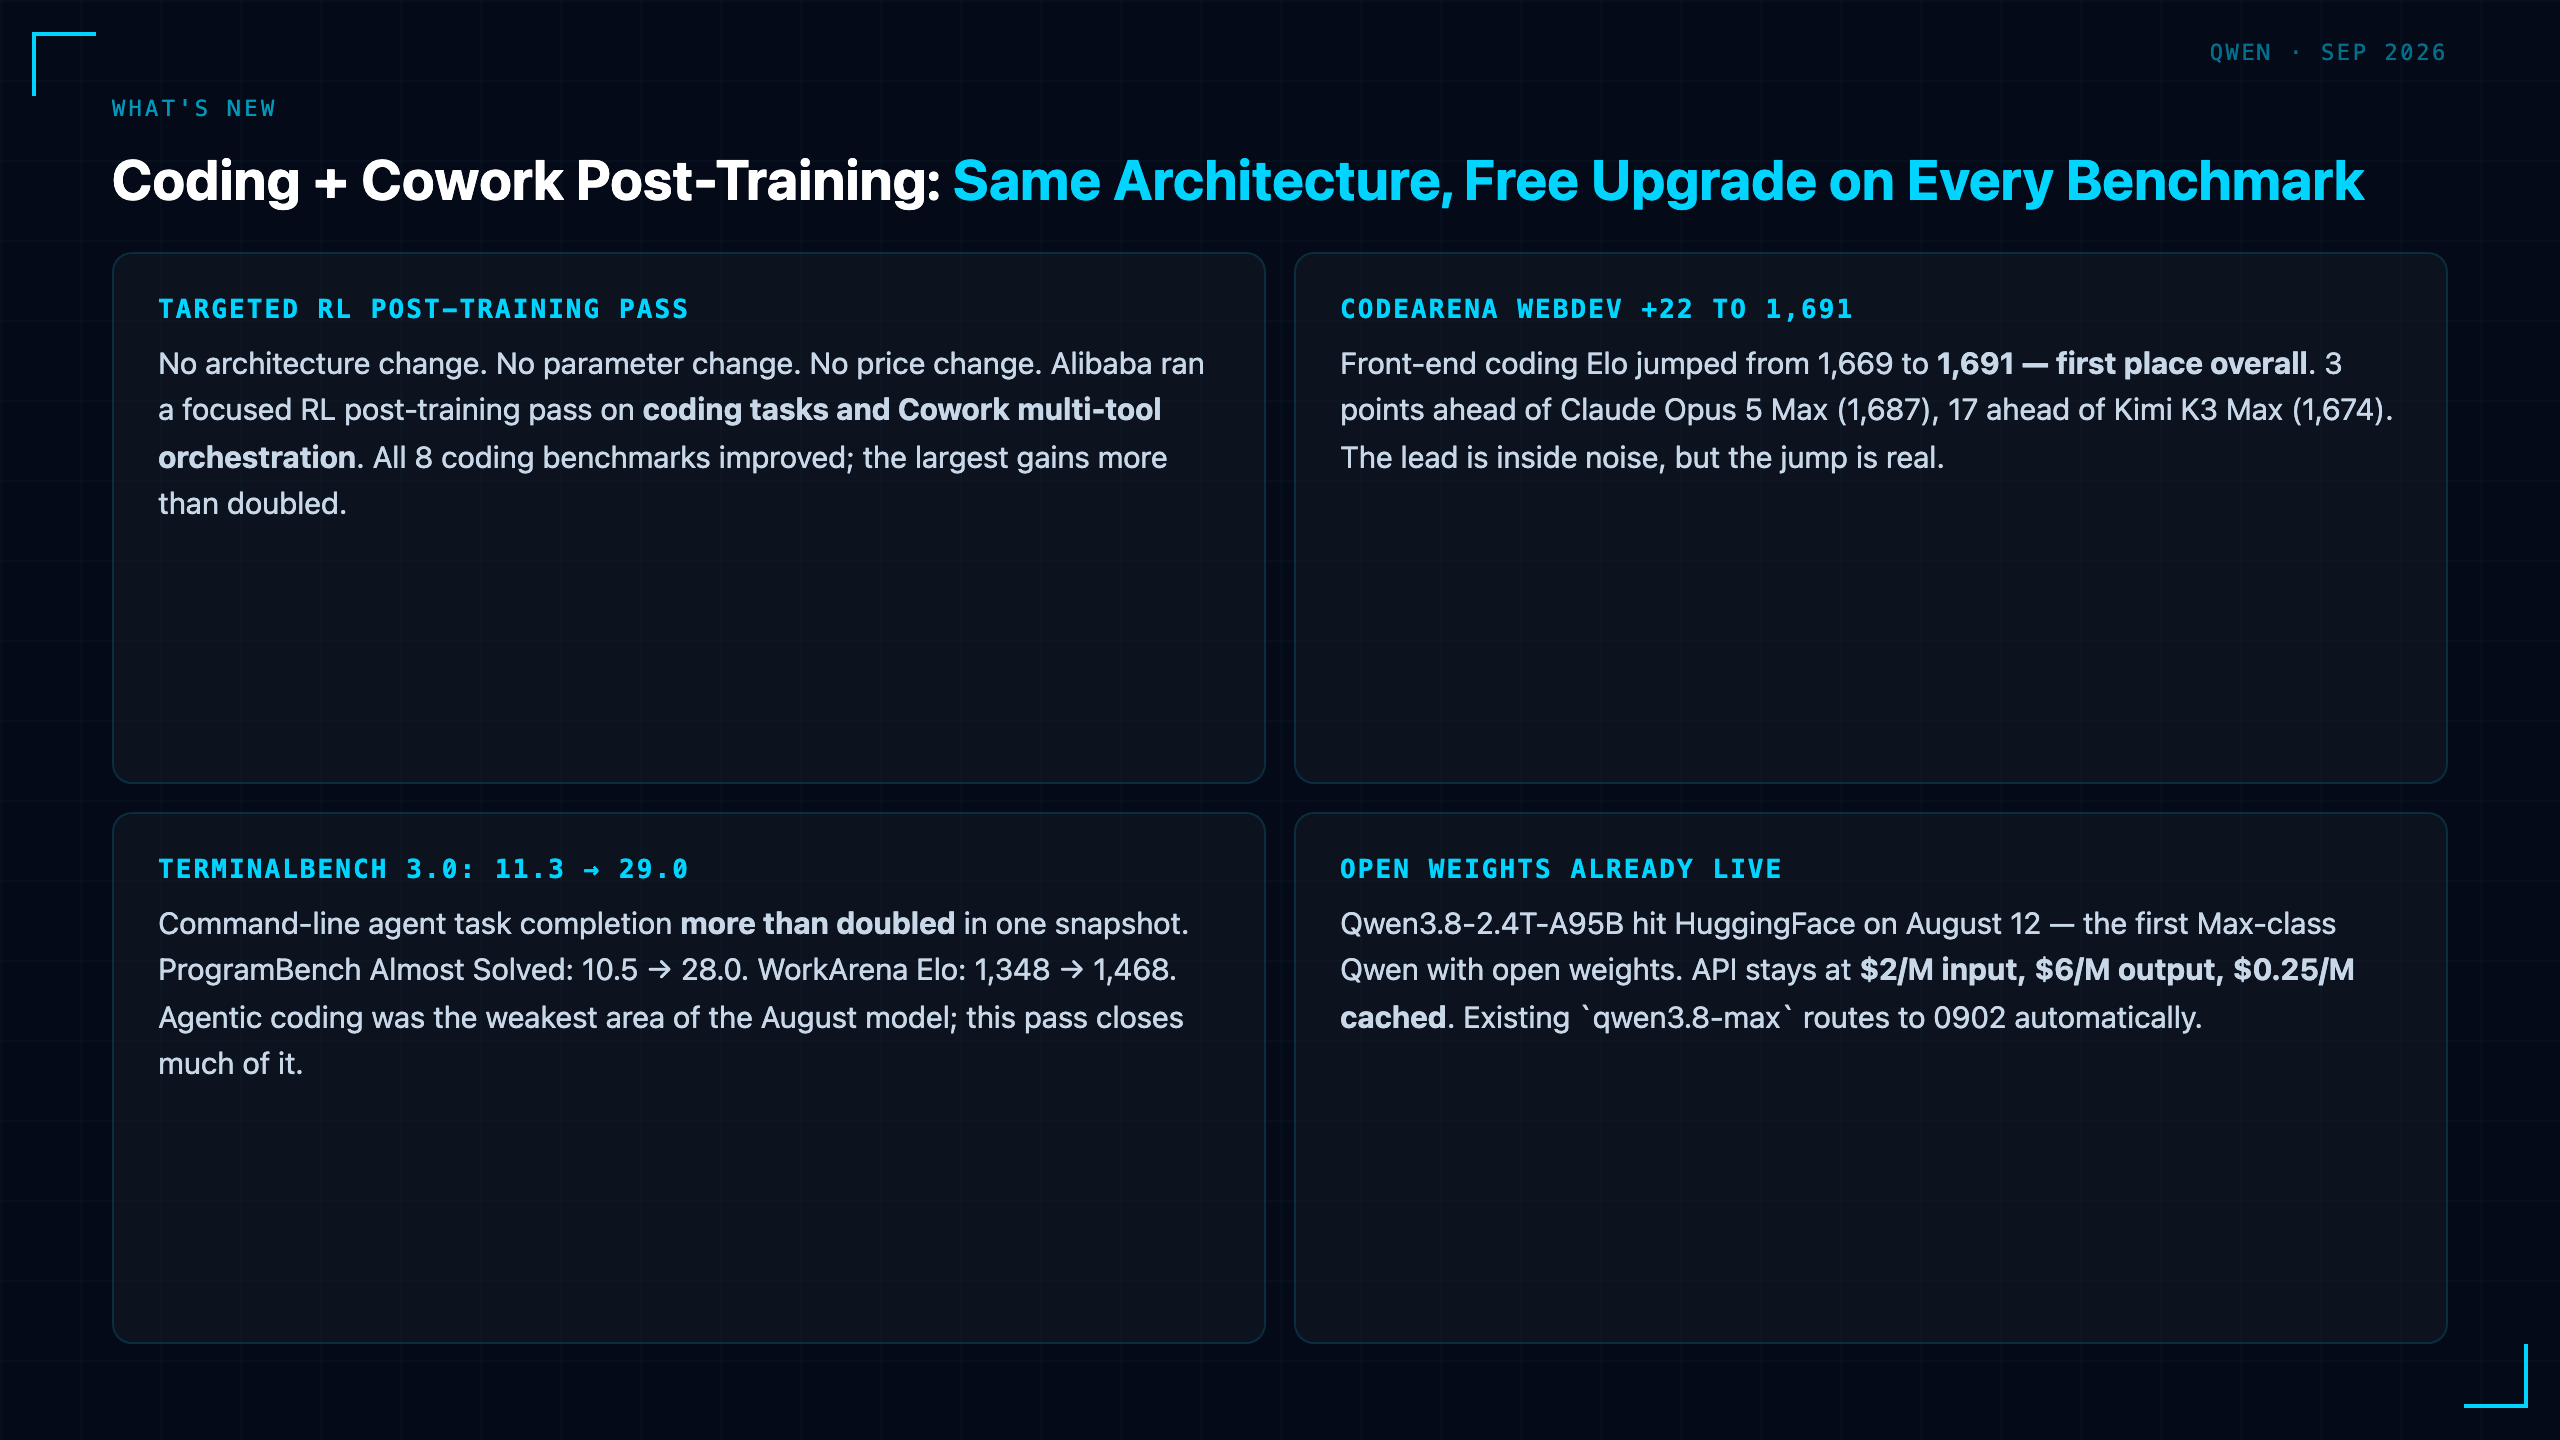
The 0902 update is deliberately narrow. Alibaba did not touch the architecture, did not change the parameter count, did not move the context window, and did not adjust pricing. What changed is the post-training recipe: a targeted reinforcement learning pass on coding tasks and Cowork scenarios — multi-tool orchestration, long-horizon agent execution, and professional office workflows.
What stayed the same:
| Spec | Value |
|---|---|
| Total parameters | 2.4T (MoE) |
| Active parameters per token | 95B |
| Context window | 1M tokens |
| Input price | $2.00 / M tokens |
| Output price | $6.00 / M tokens |
| Implicit cache | $0.25 / M tokens |
| API model ID | qwen3.8-max-0902 |
| Open weights | Qwen3.8-2.4T-A95B on HuggingFace (released Aug 12) |
What changed: the post-training data mix. According to DataCamp's analysis, all eight coding benchmarks improved, with the largest gains on TerminalBench 3.0 (11.3 → 29.0) and ProgramBench Almost Solved (10.5 → 28.0) — both more than doubling. The signal is clear: Alibaba found a post-training recipe that compounds on agentic coding without degrading the general capabilities that Qwen3.8-Max already had.
The Cowork angle matters. Qwen frames the 0902 pass as improving both coding and professional office work — tool orchestration, document processing, multi-step enterprise tasks. WorkArena Elo climbed from 1,348 to 1,468, and CoWorkBench moved from 74.8 to 76.1. This is not just a coding model; it is a model tuned for the kind of long-horizon agent work that developers are actually shipping in production.
Benchmarks: The 22-Point Jump and What It Hides
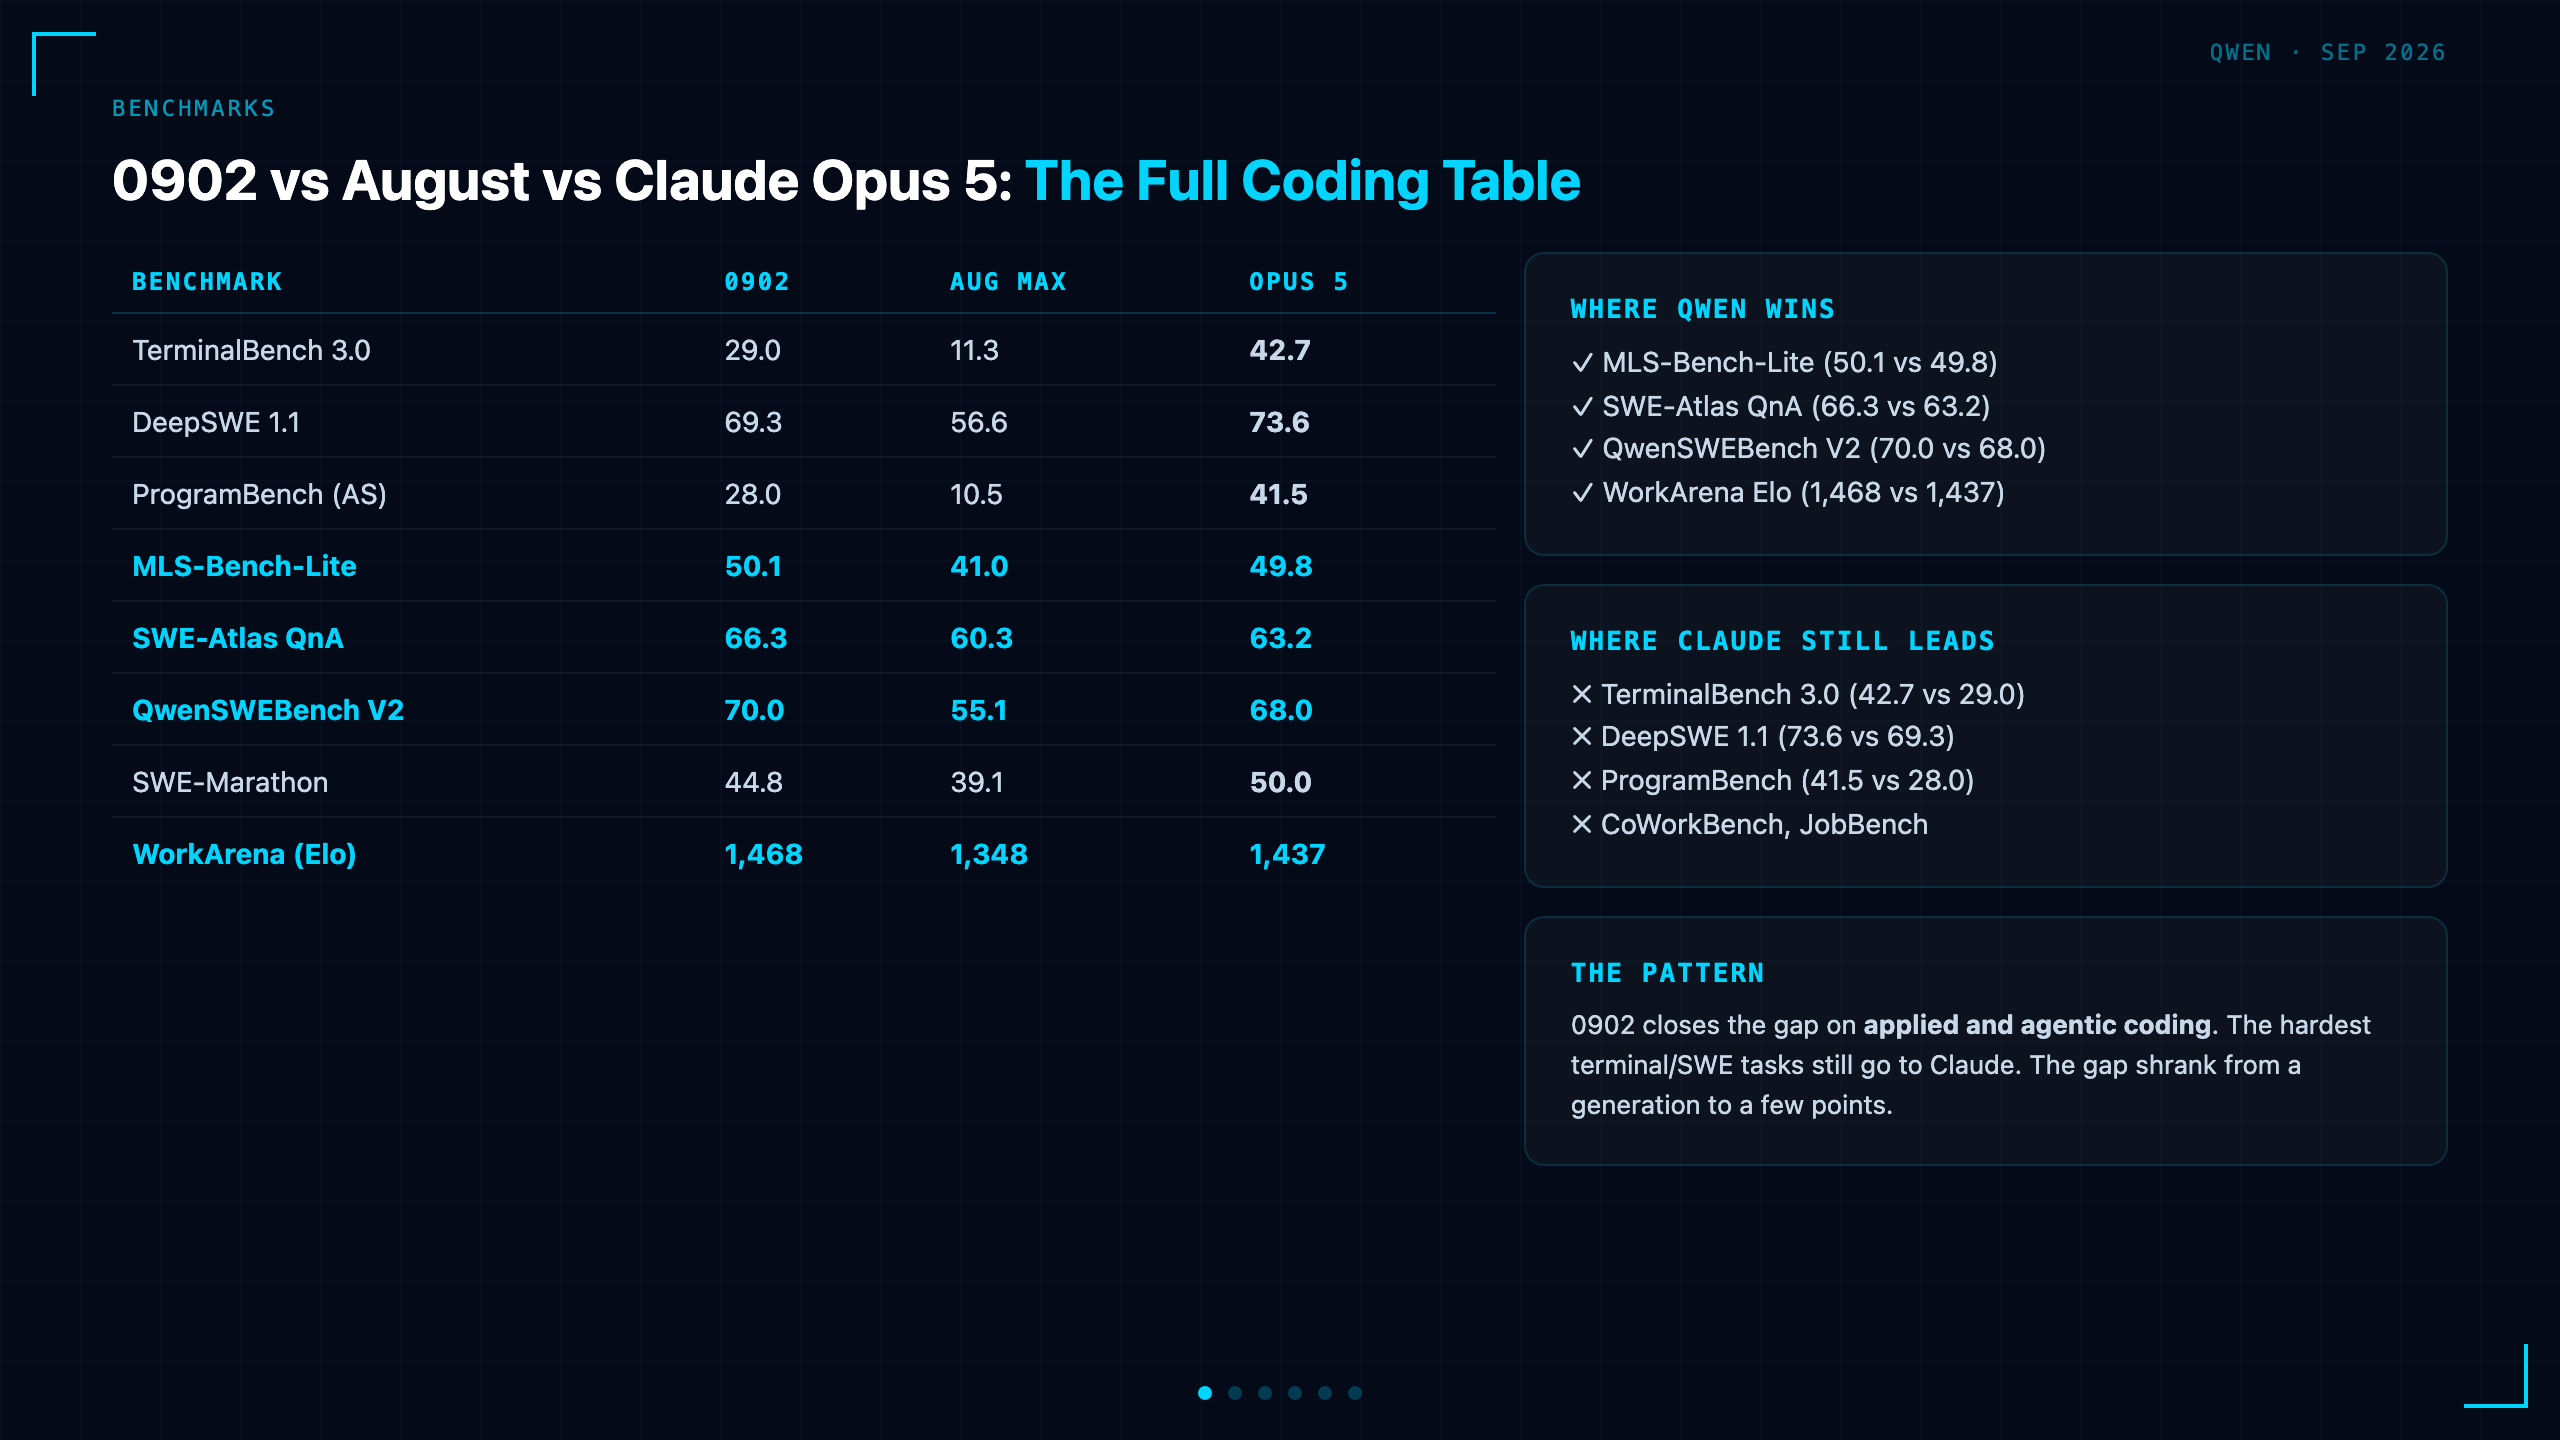
The CodeArena WebDev number is the marketing headline, but it is the least informative number in the release. Elo on a crowd-sourced front-end coding arena moves in small increments; a 22-point jump is meaningful, but the 3-point lead over Claude Opus 5 Max is not something you should build a procurement decision on. The benchmark table underneath tells a more honest story.
Coding benchmarks — 0902 vs. August Qwen3.8-Max vs. Claude Opus 5 (per Alibaba's published comparison and metirai's review):
| Benchmark | Qwen3.8-Max-0902 | Qwen3.8-Max (Aug) | Claude Opus 5 |
|---|---|---|---|
| TerminalBench 3.0 | 29.0 | 11.3 | 42.7 |
| DeepSWE 1.1 | 69.3 | 56.6 | 73.6 |
| NL2Repo-Bench | 64.9 | 55.9 | 72.3 |
| ProgramBench (Almost Solved) | 28.0 | 10.5 | 41.5 |
| SWE-Marathon | 44.8 | 39.1 | 50.0 |
| MLS-Bench-Lite | 50.1 | 41.0 | 49.8 |
| SWE-Atlas QnA | 66.3 | 60.3 | 63.2 |
| QwenSWEBench V2 | 70.0 | 55.1 | 68.0 |
Agent benchmarks:
| Benchmark | Qwen3.8-Max-0902 | Qwen3.8-Max (Aug) | Claude Opus 5 |
|---|---|---|---|
| CoWorkBench | 76.1 | 74.8 | 79.6 |
| JobBench | 64.0 | 53.4 | 67.8 |
| Toolathlon Verified | 73.3 | 72.5 | 77.6 |
| WorkArena (Elo) | 1,468 | 1,348 | 1,437 |
The pattern is worth reading carefully. Qwen3.8-Max-0902 leads Claude Opus 5 on three coding benchmarks (MLS-Bench-Lite, SWE-Atlas QnA, QwenSWEBench V2) and wins WorkArena by 31 Elo points. But on the hardest terminal agent task (TerminalBench 3.0), Claude Opus 5 still leads by 13.7 points — and on DeepSWE 1.1, the gap is 4.3 points. The 0902 pass closed the gap on agentic coding, it did not close it on the hardest SWE-style tasks.
The TerminalBench 3.0 jump from 11.3 to 29.0 is the single most striking number in the release. That is a 2.6× improvement on a benchmark that measures command-line task completion under time pressure. But it also means Qwen3.8-Max was at 11.3 just a month ago — which should temper any assumption that the August model was already at the frontier on agentic terminal work.
Comparison: Qwen3.8-Max-0902 vs. DeepSeek V4 Pro, Kimi K3, Claude Opus 5
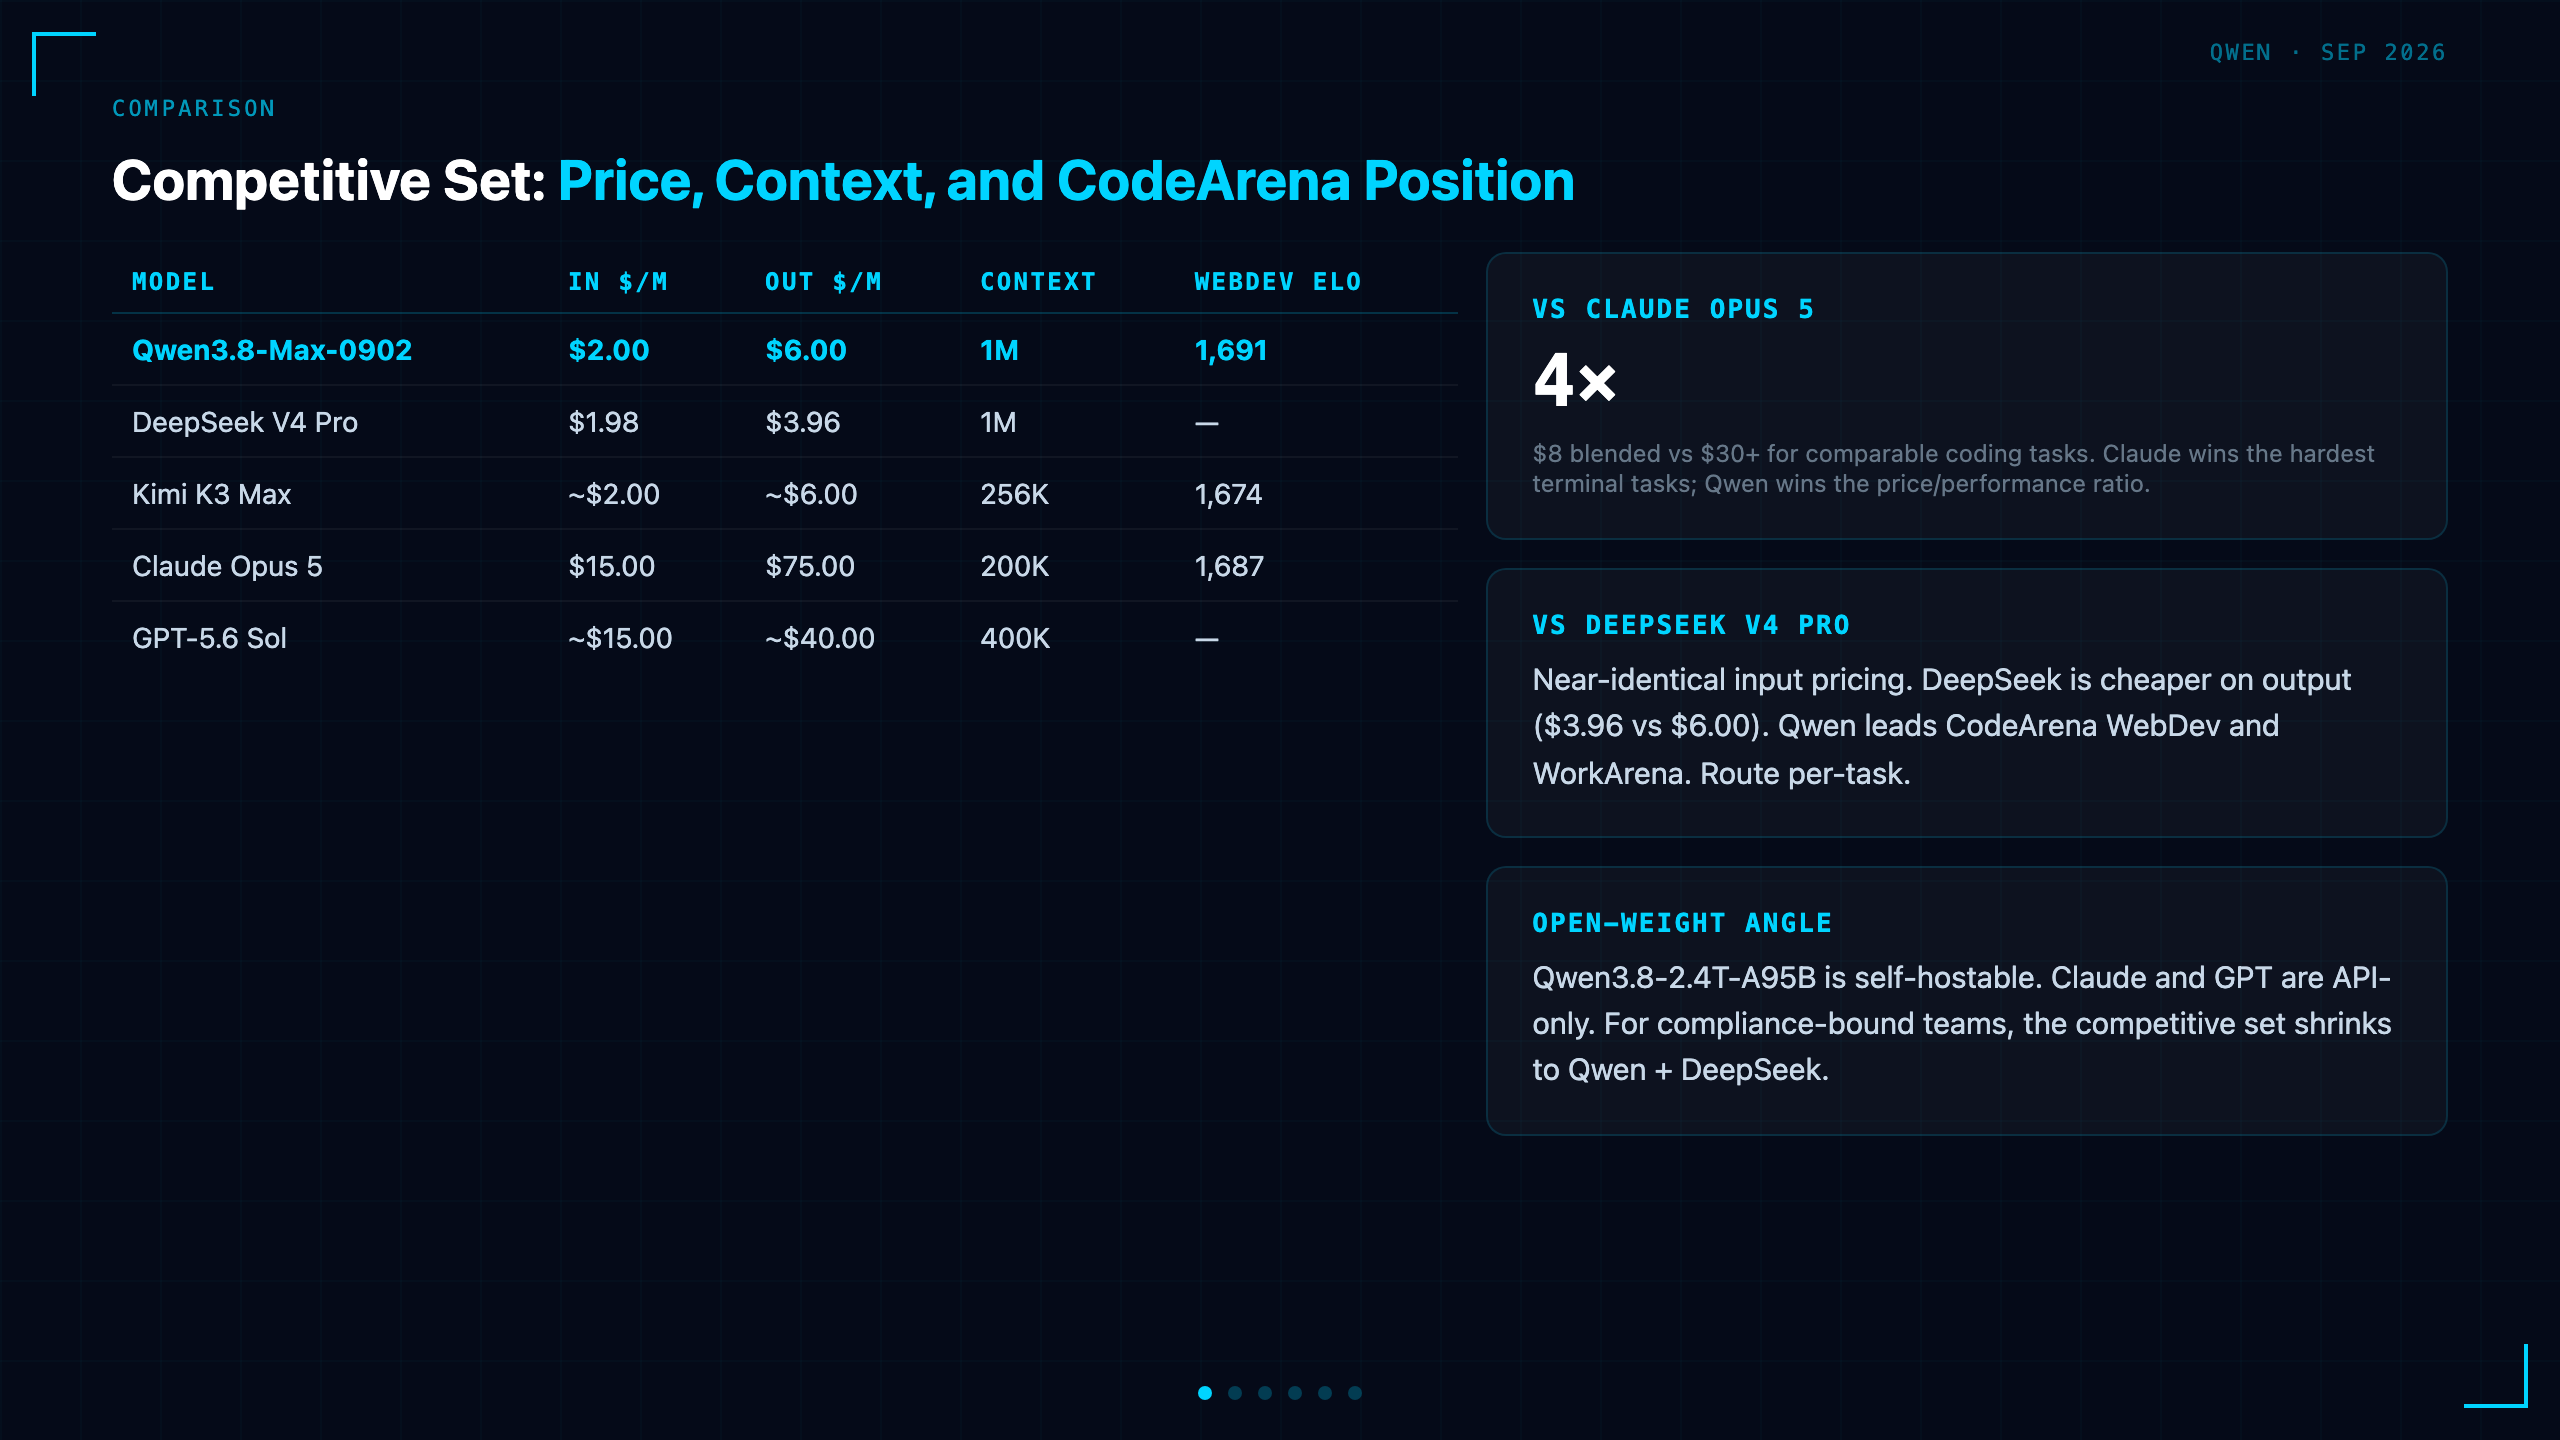
The competitive set for a 2.4T MoE flagship at $2/$6 is narrow. The models that matter for the comparison are the ones developers are actually routing production coding traffic to.
Price and positioning:
| Model | Input $/M | Output $/M | Total blended | Context |
|---|---|---|---|---|
| Qwen3.8-Max-0902 | $2.00 | $6.00 | $8.00 | 1M |
| DeepSeek V4 Pro | $1.98 | $3.96 | $5.94 | 1M |
| Kimi K3 Max | ~$2.00 | ~$6.00 | ~$8.00 | 256K |
| Claude Opus 5 | $15.00 | $75.00 | $30.00+ | 200K |
| GPT-5.6 Sol Standard | ~$15.00 | ~$40.00 | ~$35.00 | 400K |
Qwen3.8-Max-0902 sits in the middle of the Chinese flagship pack. DeepSeek V4 Pro is cheaper on output ($3.96 vs. $6.00), but Qwen leads on several coding benchmarks. Kimi K3 Max is the direct peer on CodeArena WebDev (1,674 Elo vs. Qwen's 1,691). Claude Opus 5 is the quality ceiling — and roughly 4× more expensive on a blended basis.
Coding benchmark comparison across the competitive set (SWE-bench Pro and TerminalBench 2.1 from Qwen's original August release, updated for 0902 where available):
| Benchmark | Qwen3.8-Max-0902 | DeepSeek V4 Pro | Kimi K3 Max | Claude Opus 5 |
|---|---|---|---|---|
| CodeArena WebDev (Elo) | 1,691 | — | 1,674 | 1,687 |
| TerminalBench 3.0 | 29.0 | — | — | 42.7 |
| TerminalBench 2.1 | 86.6 | — | — | 84.6 |
| SWE-bench Pro | 67.7 | — | — | 69.2 |
| DeepSWE 1.1 | 69.3 | — | — | 73.6 |
| WorkArena (Elo) | 1,468 | — | — | 1,437 |
The honest read: Qwen3.8-Max-0902 is now the price/performance leader on front-end and agentic web development, tied with Kimi K3 and slightly ahead of Claude Opus 5 on the specific arena that developers vote on. But Claude Opus 5 still holds the lead on the hardest terminal and SWE benchmarks — and it does so at 4× the price. For most production coding workloads, the 0902 snapshot is now the rational default unless you are specifically hitting the terminal agent tasks where Claude still wins.
The open-weight angle is the wild card. Qwen3.8-2.4T-A95B hit HuggingFace on August 12, making this the first Max-class Qwen model available for self-hosting. Claude Opus 5 and GPT-5.6 Sol are API-only. If you need on-prem deployment for compliance or cost control, the competitive set shrinks to Qwen and DeepSeek.
What It Means for Developers
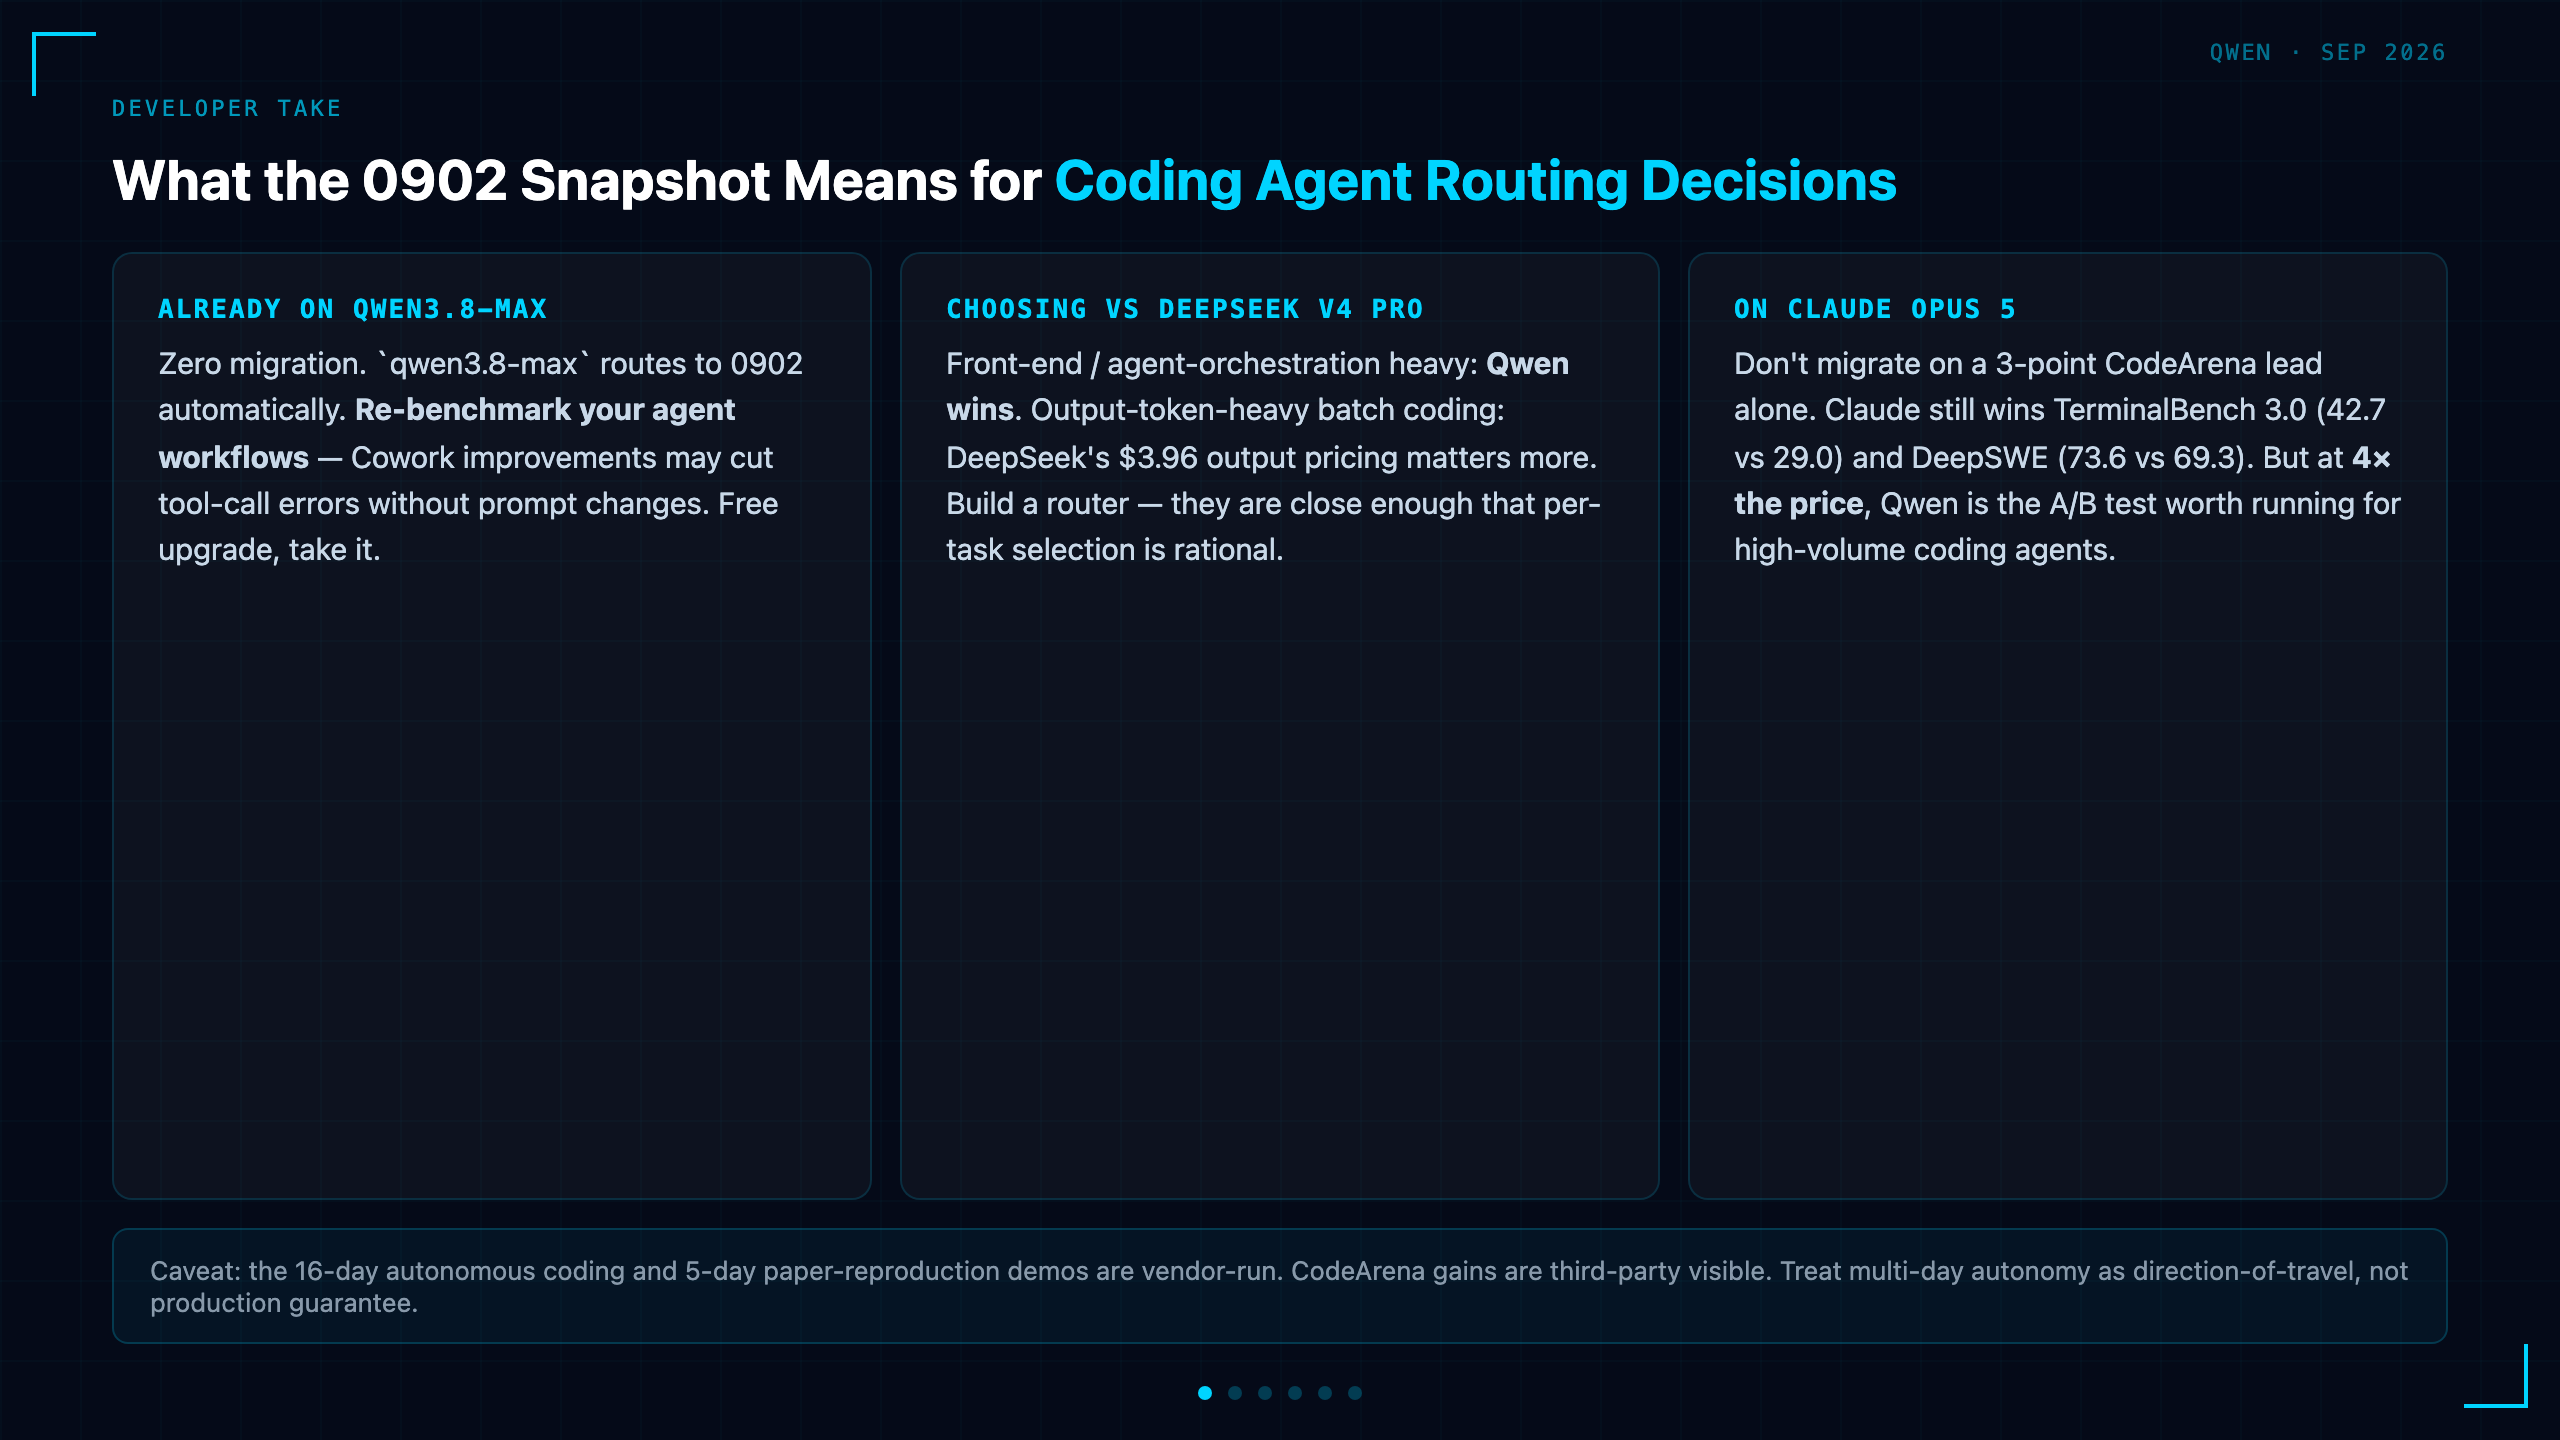
For developers choosing a coding model this September, the 0902 snapshot changes the routing math.
If you are already on Qwen3.8-Max: nothing to do. The model ID qwen3.8-max silently routes to 0902 on QwenCloud. You get the 22-point CodeArena jump, the 2.6× TerminalBench improvement, and WorkArena +31 Elo for free. Check your agent workflows — the Cowork improvements may reduce tool-call errors without any prompt changes.
If you are choosing between Qwen3.8-Max-0902 and DeepSeek V4 Pro: DeepSeek is cheaper on output ($3.96 vs. $6.00/M) and has a strong open-weight story. Qwen leads on CodeArena WebDev and WorkArena. If your workload is front-end heavy or agent-orchestration heavy, Qwen wins. If it is output-token-heavy batch coding, DeepSeek's output pricing matters more. Route accordingly — the two models are close enough that a router should pick per-task.
If you are on Claude Opus 5 for coding: The 3-point CodeArena lead Qwen claims is not a reason to migrate on its own. Claude still leads TerminalBench 3.0 (42.7 vs. 29.0), DeepSWE 1.1 (73.6 vs. 69.3), and the agent coordination benchmarks. But the cost gap is 4×. For teams running high-volume coding agents where marginal quality on the hardest 10% of tasks is not worth 4× the bill, Qwen3.8-Max-0902 is now a legitimate alternative to test.
If you need self-hosted: Qwen3.8-2.4T-A95B is the first Max-class open-weight Qwen. The license terms were not fully disclosed at the August launch, but the weights are on HuggingFace. For teams that cannot send code to third-party APIs, this is the only open-weight option at this level of coding capability — DeepSeek V4 Pro's open weights trail the API version on several benchmarks.
One caveat worth flagging: the 16-day autonomous coding showcase and the 5-day research reproduction demo from the August launch are vendor-run. The 0902 post-training improvements are real and third-party visible on CodeArena, but the multi-day unattended engineering claims have not been independently reproduced. Treat those as direction-of-travel signals, not production guarantees.
Bottom Line
Qwen3.8-Max-0902 is a textbook post-training play: same 2.4T/95B architecture, same 1M context, same $2/$6 pricing — but a 22-point CodeArena jump to 1,691 (first place), a 2.6× TerminalBench 3.0 improvement, and WorkArena +31 Elo. It leads Claude Opus 5 on MLS-Bench-Lite, SWE-Atlas QnA, QwenSWEBench V2, and WorkArena, while Claude still wins the hardest terminal and SWE tasks at 4× the price. For developers shipping coding agents, this is now the price/performance default on the front-end and web-development side of the house — with the open-weight option as a bonus.
Resources
- Qwen3.8-Max Official Blog — Alibaba's original launch announcement and benchmark tables
- QwenCloud API — API access, model ID
qwen3.8-max-0902, OpenAI-compatible endpoint - Qwen3.8-2.4T-A95B on HuggingFace — open weights for the Max-class model
- metirai: Qwen3.8-Max-0902 Examined — independent analysis of the post-training pass
- DataCamp: Qwen3.8-Max Guide — full benchmark table and pricing breakdown
Qwen3.8-Max-0902 is available via API at QwenCloud. Pricing: $2.00/M input, $6.00/M output, $0.25/M cached. 1M context window. Open text weights on HuggingFace.